
I lead research, product, and engineering teams building agents for long-horizon, real-world work, and the environments, experience, and self-improvement that make them better over time. We carry that research into products used by millions across the Gemini ecosystem, and into internal agents powering mission-critical work at Google.
Research in Production
Agents that Engineer
Brought our agents into production on Google’s most critical infra buildout, hill-climbing on Physical-Engineering’s Last Exam, our open benchmark where every frontier model still scores below 50%.
Agents that Research
Developed Test-Time Diffusion Deep Researcher, powering Gemini Deep Research (Enterprise & Max), featured on Alphabet’s Q1 2026 earnings call.
Agents that Remember
Launched MemoryBank, long-term memory for agents, one of the most used GenAI APIs on Google Cloud, powering Gemini Enterprise and BigQuery, highlighted at Google Cloud NEXT 2026.
Also shipped
- Distilling Step-by-Step, which teaches smaller Gemini models to reason like larger ones.
- Heterogeneous Swarms, which learns how multiple LLMs divide roles, in Gemini Enterprise Agent Designer, announced by the Google Cloud CEO.
Research Agenda
Today's agents are strong at short tasks but weak at getting better over time and at real-world work. Our teams focus on closing that gap:
- Environments are the bottleneck. Agents can only learn from the worlds we give them, and most are static. EnvHarness turns static data and tools into interactive environments.
- Experience should transfer. ReasoningBank distills reusable insights from successes and failures; SkillOS curates the skills worth carrying to the next task.
- Agents should improve themselves, safely. Harness2 lets agents build their own harnesses; VeriHarness and RRSI keep that improvement verifiable, stable, and under human oversight.
- The physical world is the next test. Humanity’s Last Exam tests knowledge; Agents’ Last Exam tests digital work. Physical-Engineering’s Last Exam tests the work behind the skyscrapers, power grids, and chip fabs we rely on, judged by what a licensed engineer would sign off on.
Earlier Work
I've worked on deep learning since my PhD at UC San Diego, advised by Zhuowen Tu with mentorship from Simon Osindero, where my work on Deeply-Supervised Nets later received the AISTATS 2025 Test-of-Time Award. I then joined the AI Research Group at Magic Leap with Andrew Rabinovich, and later Apple, where I launched foundational features for ARKit (now powering Vision Pro) and published the group's first-ever research paper, at CVPR (featured by Apple ML Journal).

Selected Talks
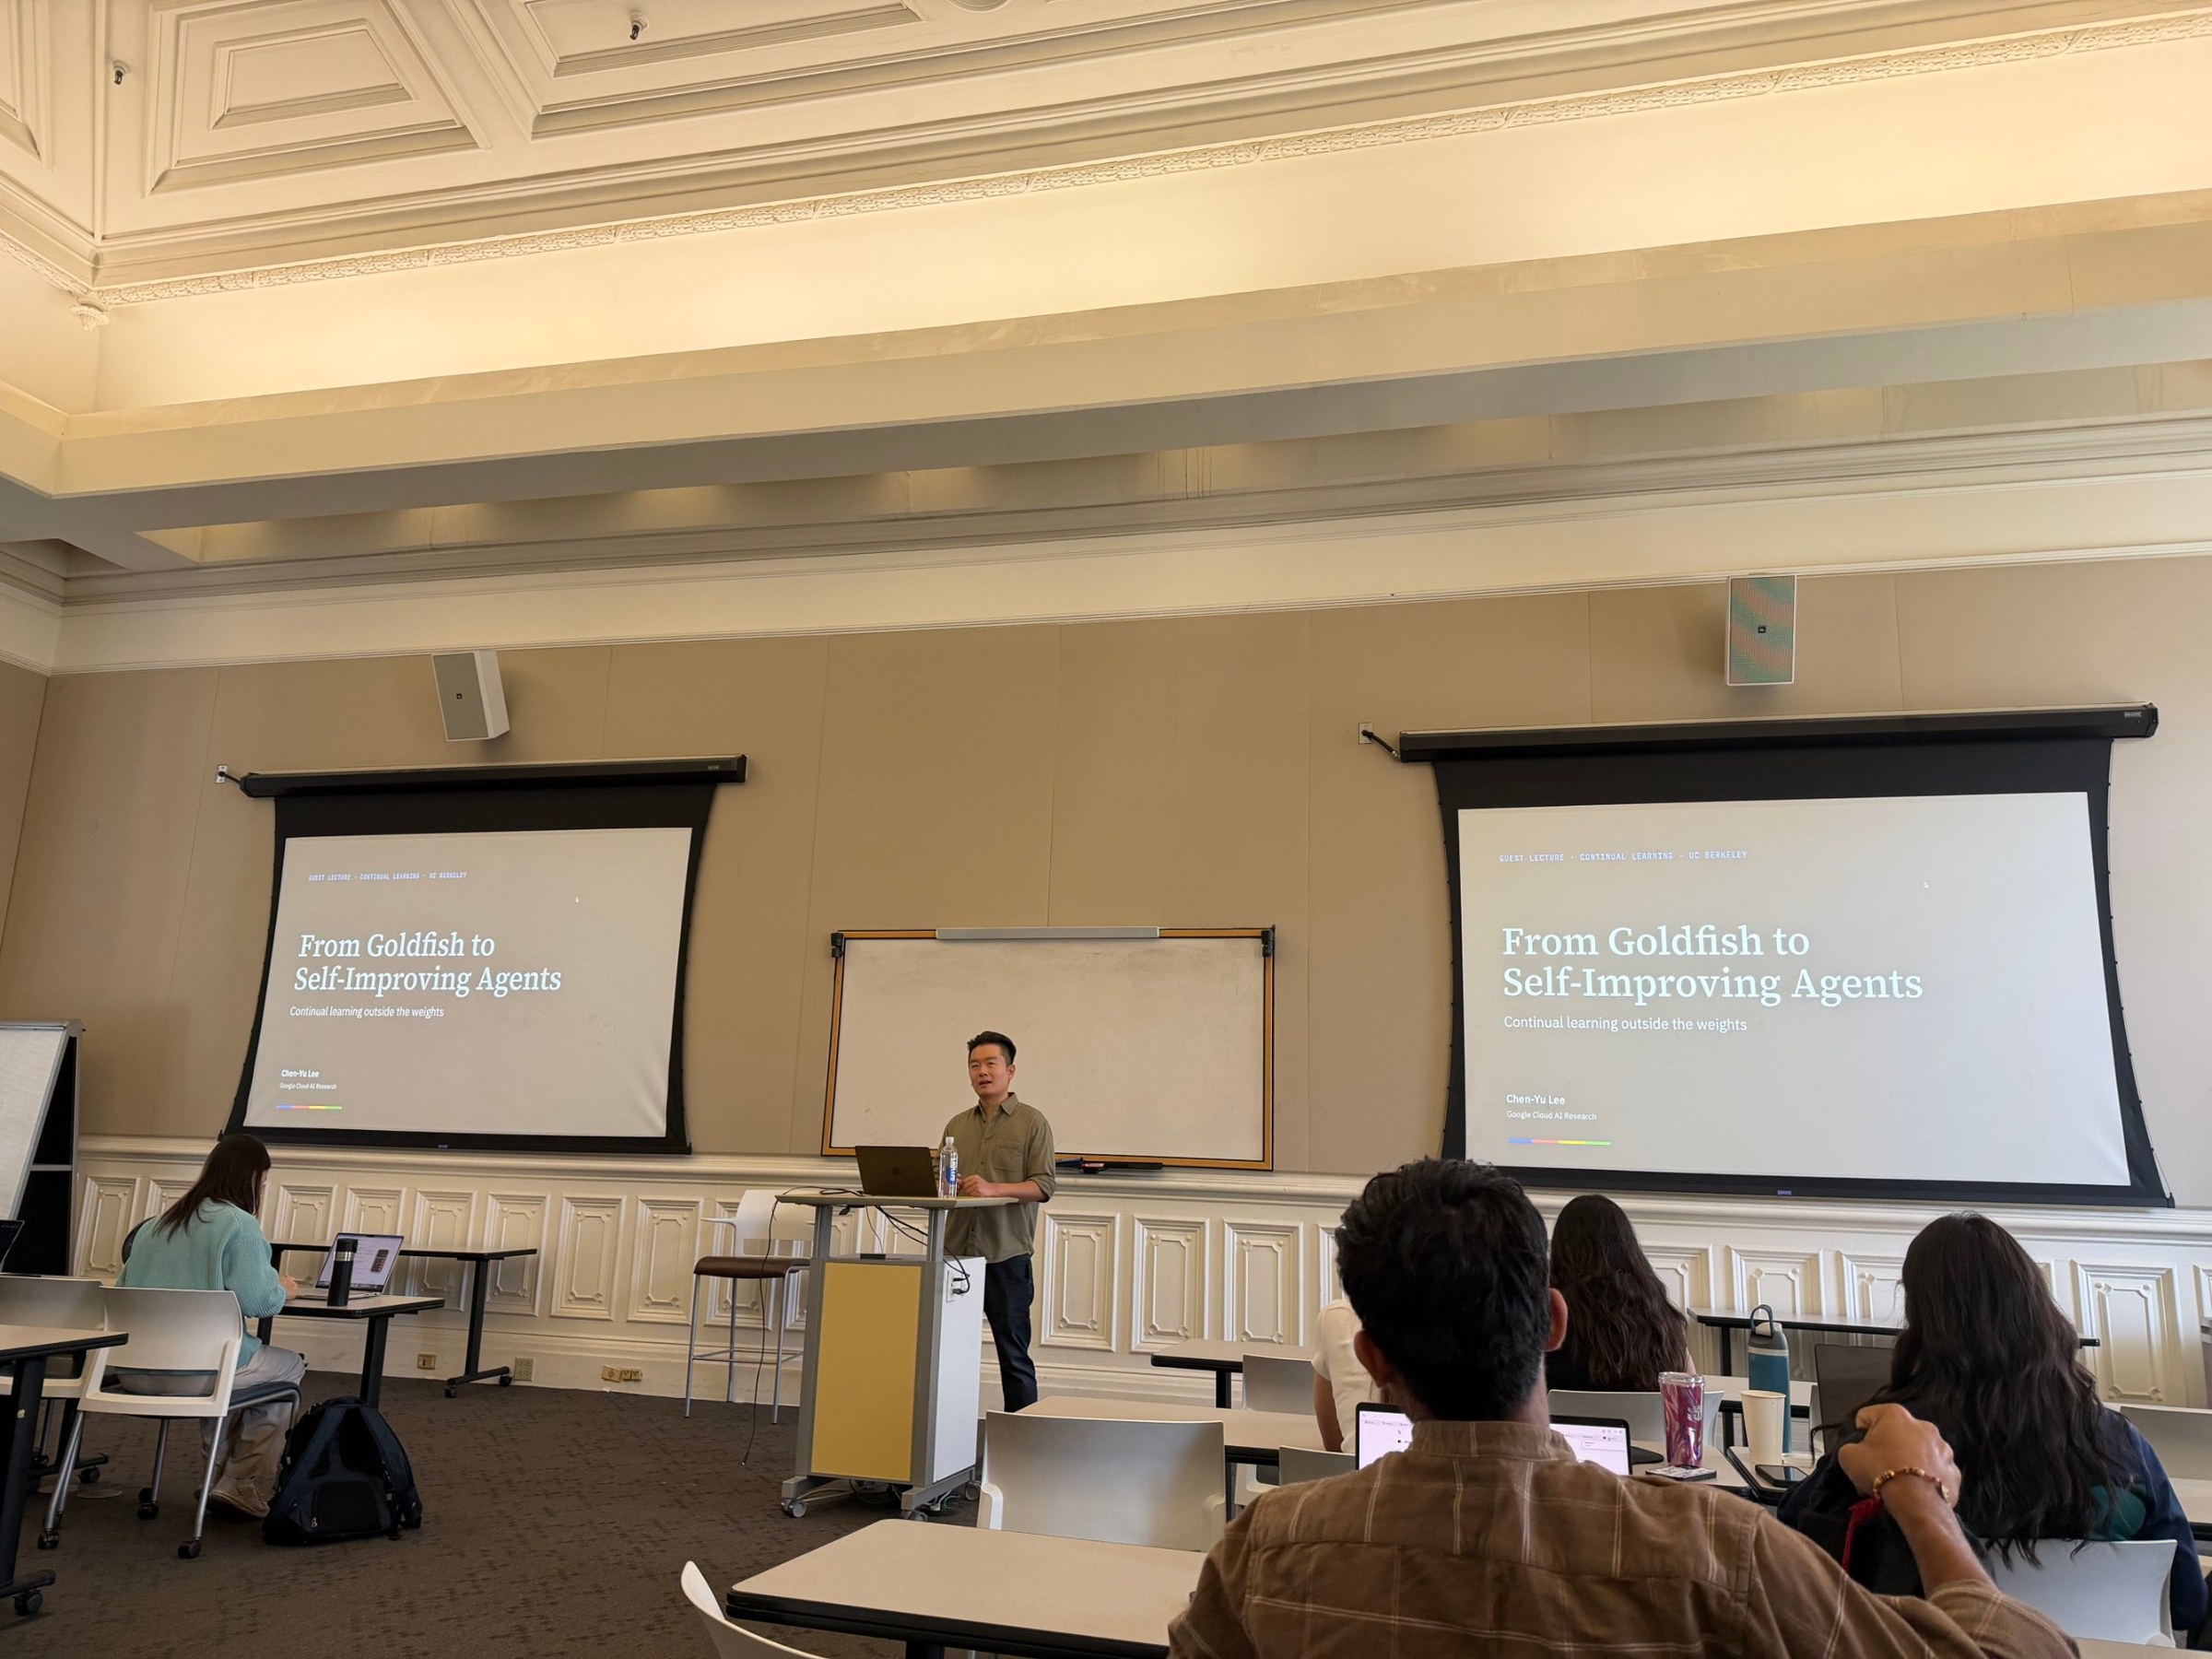
From Goldfish to Self-Improving Agents, a Fall 2026 guest lecture at UC Berkeley on continual learning and safe self-improvement.

Agent Fundamentals, Expo Talk at NeurIPS 2025, on deep research, memory, and multi-agent systems in Gemini Enterprise.

Test-of-Time Award talk at AISTATS 2025, revisiting Deeply-Supervised Nets a decade on (announcement · award · UCSD News).

Keynote at The Google School for Leaders 2026, on turning research into product impact.
Selected Papers
PLE: Physical-Engineering's Last Exam
Tests agents on real physical engineering work. Every frontier model scores below 50%. arXiv 2026 · Paper · Project Page · Code · Dataset · CompetitionRRSI: Regularized Recursive Self-Improvement of Agent Harnesses
Agents that improve their own harnesses, with regularization that keeps the loop stable. arXiv 2026 · Paper · Project Page · CodeEnvHarness: Awakening Static Worlds for Agent Learning
Turns static data and tools into interactive training environments for agents. arXiv 2026 · Paper · Project Page · CodeSkillOS: Learning Skill Curation for Self-Evolving Agents
Learns how a self-evolving agent should curate its library of reusable skills. NeurIPS 2026 · PaperReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory
Distills reusable insights from an agent's successes and failures. ICLR 2026 · Paper · Code · Google AI Blog — Featured in VentureBeat and Andrej Karpathy's interviewSupervised Reinforcement Learning: From Expert Trajectories to Step-wise Reasoning
Turns expert trajectories into step-wise rewards for learning multi-step reasoning. ICLR 2026 · Paper — Featured in VentureBeatBudget-Aware Tool-Use Enables Effective Agent Scaling
Scaling agents under explicit tool and compute budgets. COLM 2026 · Paper · Code — Featured in VentureBeatDeep Researcher with Test-Time Diffusion
The research agent behind Gemini Enterprise Deep Research and Gemini Deep Research Max. arXiv 2025 · Paper · Google AI Blog — Featured in VentureBeatSpeculative Knowledge Distillation: Bridging the Teacher-Student Gap Through Interleaved Sampling
The student proposes tokens and the teacher replaces poor ones, keeping distillation on-policy and stable. ICLR 2025 · Paper · CodeDistilling Step-by-Step! Outperforming Larger Language Models with Less Training Data and Smaller Model Sizes
Small models trained on LLM rationales outperform much larger LLMs using less data. ACL 2023 · Paper (Findings) · Code · Google AI Blog — Google ACL 2023 SpotlightDeeply-Supervised Nets
Adds supervision to hidden layers to train deep networks more effectively. AISTATS 2015 · Paper · Code — Test-of-Time Award, AISTATS 2025 (slides)NIPS 2014 DL Workshop · Paper — Oral Presentation
Honors & Awards
Test-of-Time Award at AISTATS 2025
Google Spotlight Award at ACL 2023
Oral: NAACL 2025, ACL 2021, NIPS 2014 DL Workshop
Google Spotlight Award at ACL 2023
Oral: NAACL 2025, ACL 2021, NIPS 2014 DL Workshop
Academic Service
Reviewer: NeurIPS, ICML, ICLR, ACL, NAACL, EMNLP, COLM, CVPR, ICCV, ECCV, BMVC, PAMI, IJCV, JMLR
Outstanding Reviewer: CVPR 2019, BMVC 2019